The 2026 Conference on Empirical Methods in Natural Language Processing (EMNLP 2026) took place in Budapest, Hungary, from 24 to 29 October 2026. It is one of the leading international research conferences in the field of natural language processing (NLP). During the conference, Dr. Milena Stróżyna presented the paper entitled “Multi-Model Framework for Sentiment Annotation: A Use Case of Multilingual Wikipedia”. The study introduces an approach in which multiple artificial intelligence models act as independent annotators, with agreement between their predictions used to identify reliable sentiment labels.
Manual annotation of text data is expensive and time-consuming, which has led to growing interest in using large language models (LLMs) to automate the process. However, their predictions can vary between models and even across repeated runs of the same model. To address this challenge, the authors proposed a framework in which several models act as independent annotators. In the study, each of three models (GPT-5.2, Gemini 3.1 Pro and Claude Opus 4.6) classified the sentiment of each sentence three times. A sentiment label was considered reliable only when all nine predictions agreed. The approach was evaluated using sentences extracted from the introductory sections of Wikipedia articles in five languages: English, German, Spanish, Polish and Russian.
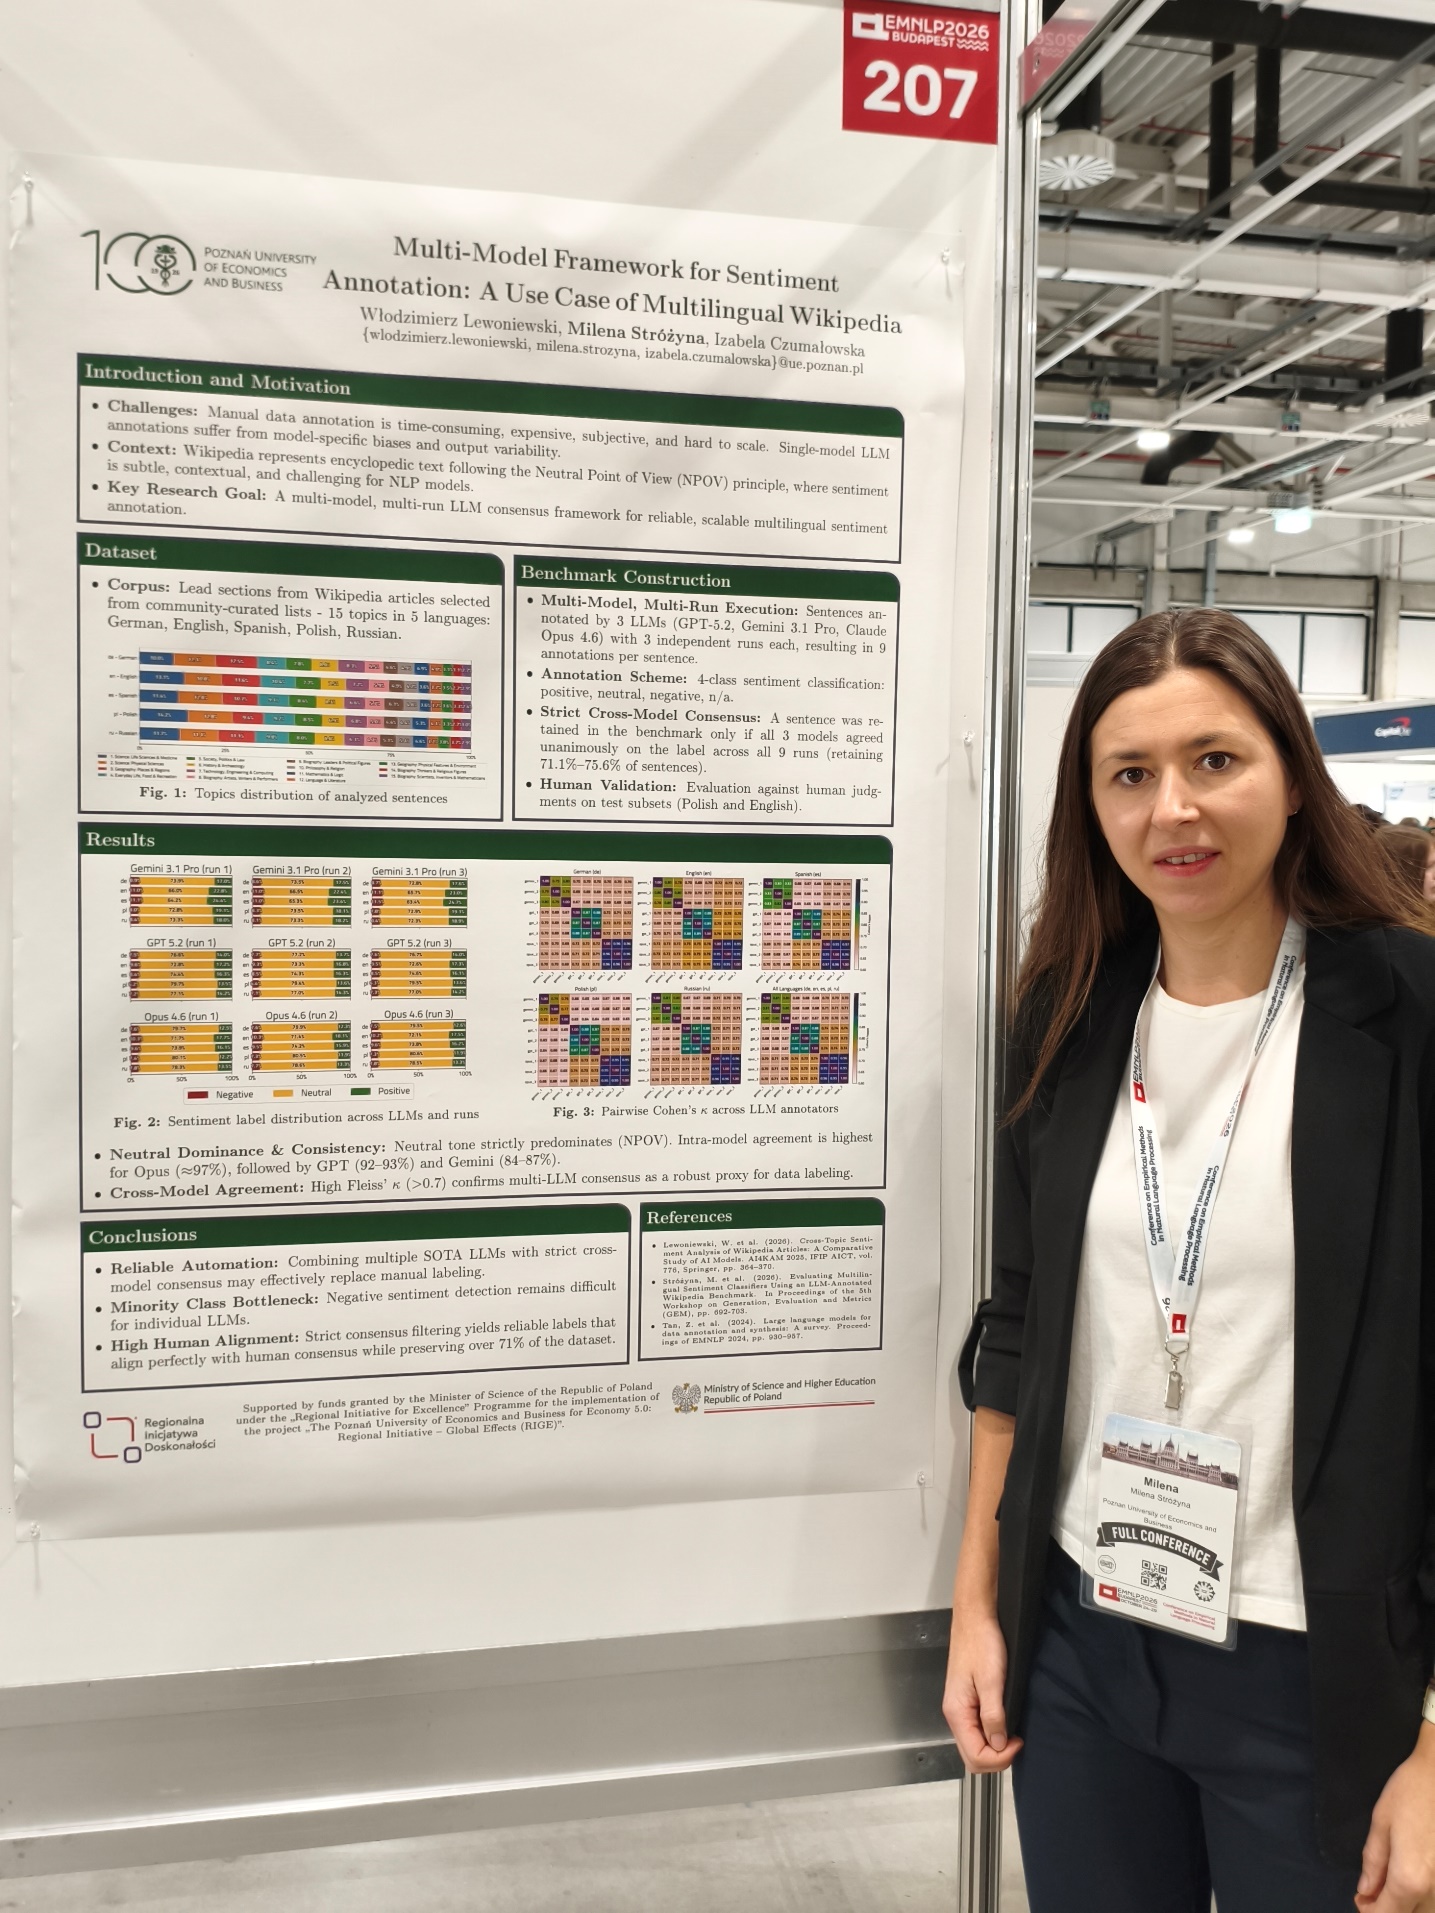 Full agreement across all nine predictions was achieved for 71% to 76% of sentences, depending on the language. Fleiss’ kappa (κ), a measure of agreement among annotators, ranged from 0.72 to 0.76. In a separate evaluation involving Polish and English text samples, sentences meeting the strict consensus criterion showed perfect agreement with human annotations. However, the analysis also revealed limitations, particularly in identifying negative sentiment, which proved more challenging for the models. The research resulted in a multilingual dataset of approximately 75,000 sentences with sentiment annotations. The dataset has been made publicly available on Hugging Face to support scalable and reproducible data annotation.
The paper was authored by Dr. Włodzimierz Lewoniewski, Dr. Milena Stróżyna and Izabela Czumałowska. The full text is available in the ACL Anthology. DOI: 10.18653/2026.findings-emnlp.1830
EMNLP is an annual conference organised by SIGDAT, a special interest group of the Association for Computational Linguistics (ACL). It is widely recognised as one of the most prestigious conferences in natural language processing and holds the highest A* rating in the CORE conference rankings. The 2026 edition was held at the Hungexpo Budapest Congress and Exhibition Centre.